AI's largest biological dataset
AI's understanding of biology was limited by the data it was trained on. To change this, we established partnerships across all seven continents to create BaseData™; the largest and most diverse evolutionary genetic dataset ever built.
The data wall holding back AI in biology
Today's biological datasets are narrow, repetitive, and heavily biased toward a small number of well studied organisms.
Much of biology's diversity remains entirely absent from the data used to train AI models.
of public data comes from just five species
of it oiginates from only ten countries
annual growth rate of the most widely used AI training database
So we built BaseData™
By establishing a network of biodiversity partners across all 7 continents, we created an evolutionary dataset of over 10 billion genes and a million uncharacterised species. This dataset gives AI models an unprecedented view of biology.
read the BaseData paper
The Trillion Gene Atlas
The Trillion Gene Atlas is one of the most ambitious biological data initiatives ever undertaken, expanding known evolutionary genetic diversity by 1000-fold across more than 100 million species worldwide.
Read the press releaseexpansion of known evolutionary genetic diversity
growth on the current BaseData corpus
species reached worldwide

Head of Production Genomics at the Wellcome Sanger Institute and Chair of the EBP International Scientific Committee
Director of Microbiology at Innovative Genomics Institute, UC Berkeley
Professor at Weill Cornell Medicine and Founder of MetaSUB International Consortium
Co-Chair of Access and Benefit-Sharing negotiations under the Convention on Biological Diversity
ABS & CBD National Focal Point and Co-Chair of the UN OEWG on Digital Sequence Information
Co-Director at the Kotahi Research Institute and Co-founder of Global Indigenous Data Alliance
Chair of African Microbiome Project and Director or the ISME Ambassador Program
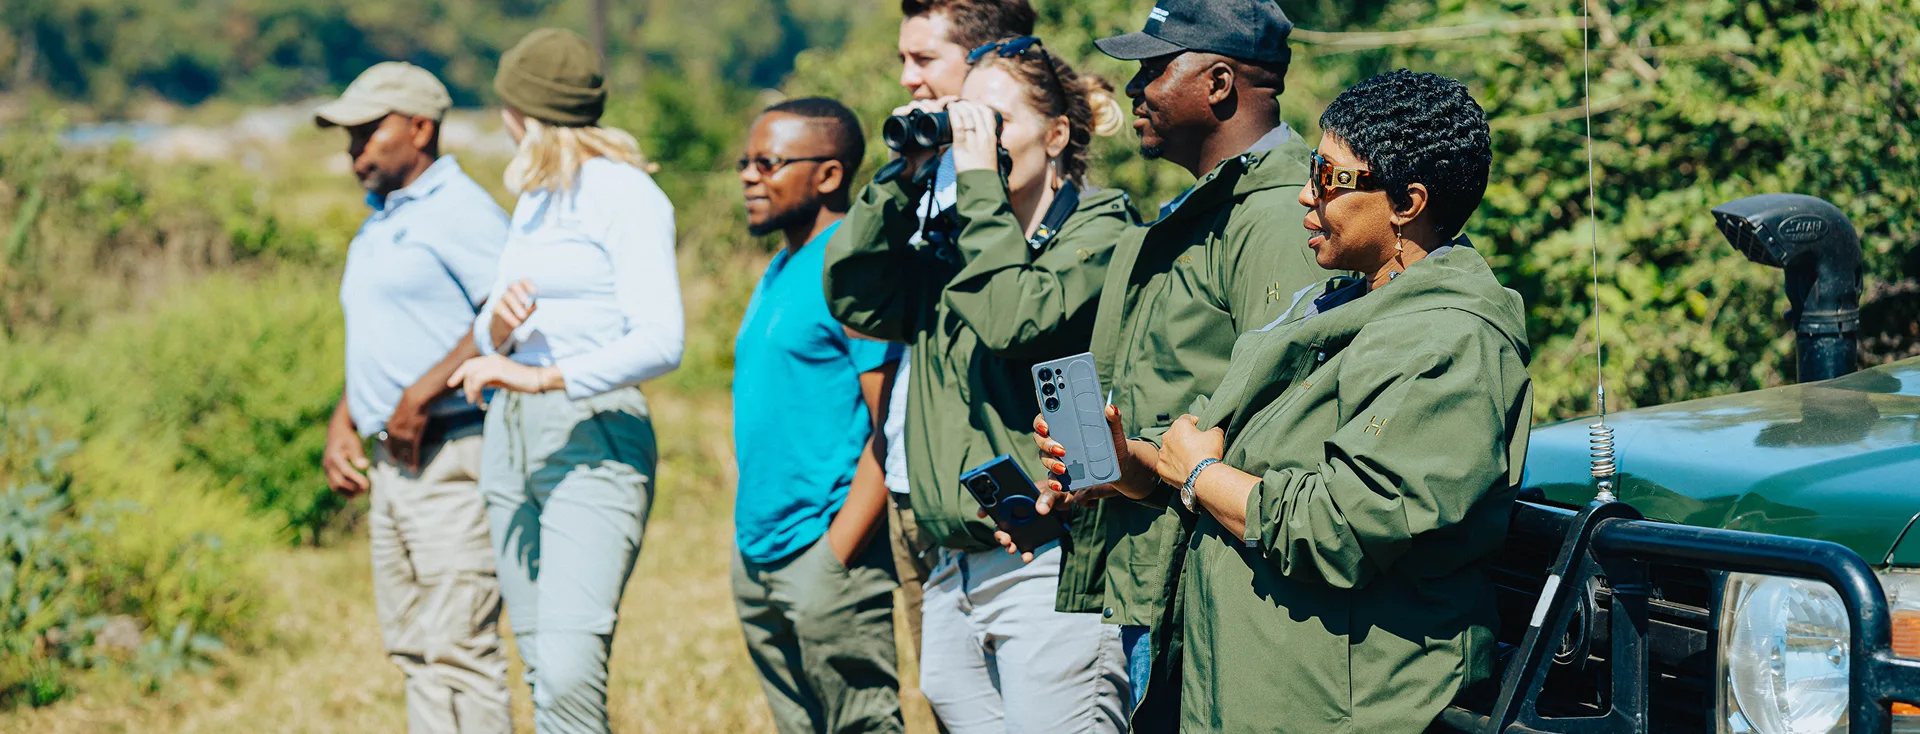
A global data network built through partnership
At the core of our data are our biodiversity partners. Every sample is collected under informed-consent and benefit-sharing agreements so that the countries and communities who steward this biodiversity share in the value it creates.
We actively contribute to discussions shaping the frameworks and policies that govern access to genetic resources, and the sharing of benefits arising from their use. This policy engagement helps ensure that our partnerships remain aligned with evolving international biodiversity governance frameworks.
ABS agreements
royalties paid to 21 countries
scientists trained
across 30+ countries